AI-InfusedAdvanced Data Science Course in Saharanpur with Gen AI
The Best Data Science Course in Saharanpur with Gen AI is a complete and career-focused training program designed to combine core data science skills with the latest advancements in Generative AI. This course helps learners build a strong foundation in data analysis, machine learning, and deep learning, along with practical knowledge of modern Gen AI tools such as ChatGPT, Large Language Models (LLMs), and AI-powered applications. With hands-on projects, expert mentorship, and real-world case studies, learners gain practical experience, industry-ready skills, and the confidence to apply data science and Gen AI concepts in real job roles. This is an online course designed for flexible and effective learning from anywhere.
Get free career counselling
Batch dates, fee, EMI plan and a personalised roadmap for Advanced Data Science Course in Saharanpur with Gen AI.
Make sure this is an active WhatsApp number. The OTP will be sent via WhatsApp.
By submitting this form, you agree to our Terms and Conditions and Privacy Policy. No spam. Your details are only used to contact you about your enquiry.
Build Industry-Ready Skills with Practical Training
AI-Infused Courses
Build industry-relevant skills with modern AI tools and technologies integrated into your learning experience.
Free LMS for 1 Year
Access class recordings, study notes, quizzes, assignments, and projects on BrillicaNext for 12 months to support continuous learning.
BrillicaNext Mobile App
Stay connected to your learning journey with convenient mobile access to course resources on Android and iOS.
Placement Support
Prepare for career opportunities with resume building, LinkedIn profile guidance, mock interviews, and placement assistance.
No-Cost EMI
Make your learning journey more accessible with convenient monthly instalments through available EMI options, subject to applicable terms.
Explore the Course Curriculum
- Data fundamentals and the pillars of data analytics
- Data Analytics vs Data Science
- Machine Learning, AI and Generative AI explained
- Data science lifecycles and workflows
- Roles and career paths in data science
- DBMS vs RDBMS, MySQL / PostgreSQL setup
- SQL command types: DDL, DML, DQL, DCL, TCL
- Data types, schemas, CRUD and loading data
- SELECT, aliases, LIMIT/OFFSET, DISTINCT
- WHERE, BETWEEN, LIKE, REGEXP and sorting
- Text, date-time, NULL and CAST functions
- GROUP BY, HAVING, WITH ROLLUP
- CASE statements and pivoting with CASE WHEN
- Set operations, constraints, keys and normalization (1NF–3NF)
- ER diagrams; inner, outer, cross, self and anti-joins
- Nested and correlated subqueries, EXISTS / ANY / ALL
- Chaining multiple CTEs
- Window functions: ROW_NUMBER, RANK, LAG, LEAD, running totals
- Views, stored procedures, temp tables, indexes and EXPLAIN
- Exporting results; MySQL with Python (pandas.read_sql)
- Setup, Jupyter Notebook, comments and variables
- Data types, type casting, input and operators
- Importing modules: random, math, datetime
- Strings, lists, tuples, sets and dictionaries
- Indexing, slicing, functions and methods
- Comprehensions and generator expressions
- Conditionals, ternary operator, loops, break/continue
- Functions, *args/**kwargs, scope (LEGB) and recursion
- Lambda and higher-order functions: map, filter, reduce, zip
- User-defined modules, packages and pip
- File handling: text, CSV and JSON
- Exception handling and custom exceptions
- Classes, objects, constructors and self
- Instance, class and static methods
- Encapsulation, inheritance, polymorphism, abstraction
- NumPy array creation, attributes and random module
- Indexing, reshaping, stacking and splitting
- Vectorisation, broadcasting and np.where / np.select
- Series and DataFrames; reading CSV, Excel, JSON and SQL
- Selection with loc / iloc, filtering and sorting
- Missing values, duplicates, string cleaning and apply()
- Binning, outlier treatment (IQR), GroupBy and agg()
- Pivot tables, crosstab, melt, merge and join
- Date-time handling, resampling and rolling windows
- Matplotlib: line, bar, area, pie, scatter and distribution charts
- Customisation, subplots and styles
- Seaborn: categorical, distribution, relational and matrix plots
- Univariate, bivariate and multivariate analysis
- Correlation, outliers and missing-value patterns
- Notation (Σ, Π, sets), functions and graphs
- Exponents, logarithms and power transformations
- Vectors, norms, dot product and cosine similarity
- Matrices, inverse, determinant, rank and vector spaces
- Eigenvalues, eigenvectors, SVD, covariance matrix and PCA
- Limits, derivatives, partial derivatives and gradients
- Chain rule — the foundation of backpropagation
- Loss functions, gradient descent and learning rate
- Entropy, information gain and cross-entropy
- Population vs sample, data and variable types
- Central tendency, dispersion, percentiles, skewness and kurtosis
- Z-scores, normal distribution, Q-Q plots and normality tests
- Log, Box-Cox, Yeo-Johnson and quantile transforms
- Standardisation, min-max and robust scaling
- Counting, conditional probability and Bayes' theorem
- PMF, PDF, CDF and key distributions (Binomial, Poisson, Normal, t, Chi-Square, F)
- Sampling, Law of Large Numbers and Central Limit Theorem
- Estimation, MLE and confidence intervals
- Hypothesis testing, p-values, errors, power and effect size
- Z / t-tests, ANOVA, Chi-Square and non-parametric tests
- Correlation vs causation, bootstrap and Monte Carlo
- A/B testing and experimental design
- SciPy and Statsmodels on real-world datasets
- Garbage in, garbage out and the CRISP-DM workflow
- Features vs target and types of ML problems
- Automated profiling with ydata-profiling and Sweetviz
- Cardinality, constant and correlated features
- Target-driven analysis and feature interactions
- Missingness mechanisms (MCAR, MAR, MNAR) and imputation
- Outlier engineering with Isolation Forest and LOF
- Categorical encoding and high-cardinality handling
- Multicollinearity (VIF), scaling and domain features (RFM)
- Feature selection: filter, wrapper and embedded methods
- Imbalanced data: SMOTE, ADASYN and class weights
- Data leakage, splits, cross-validation and Scikit-learn pipelines
- Types and categories of ML algorithms
- Problem formulation, overfitting and the bias-variance trade-off
- Simple, multiple and polynomial regression
- Ridge, Lasso and Elastic Net; MAE, RMSE, R²
- Logistic regression, KNN, Naive Bayes, SVM and decision trees
- Confusion matrix, precision, recall, F1 and ROC-AUC
- Random Forest, AdaBoost, GBM, XGBoost, LightGBM, CatBoost, stacking
- Cross-validation, Optuna tuning and model selection
- K-Means, hierarchical, DBSCAN and GMM clustering
- PCA, t-SNE, UMAP, anomaly detection and recommenders
- ARIMA, SARIMA, Holt-Winters and Prophet
- SHAP, PDP / ICE and end-to-end pipelines
- Kaggle: Titanic, House Prices, Spaceship Titanic
- DevOps vs MLOps and maturity levels
- Batch vs real-time inference; canary and blue-green deployment
- Modular project structure and environments
- Config, logging, type hints, pytest and data validation
- Git and GitHub workflows for ML
- MLflow experiment tracking and model registry
- DVC data versioning; Pickle, Joblib and ONNX
- Streamlit and Gradio apps
- FastAPI ML APIs with Pydantic
- Docker, Docker Compose and Kubernetes basics
- GitHub Actions, Airflow and Prefect
- Deploying on Render, Hugging Face, AWS, Azure and GCP
- Prediction logging, Prometheus and Grafana
- Data and model drift with Evidently AI
- Perceptron, MLP, forward propagation and activations
- Loss functions and backpropagation from scratch
- Optimisers (SGD, Adam, AdamW) and initialisation
- Schedulers, dropout, batch norm and tuning
- TensorFlow, Keras callbacks and TensorBoard
- PyTorch tensors, autograd and training loops
- CNNs, data augmentation and famous architectures
- Object detection with YOLO and image segmentation (U-Net)
- RNN, LSTM, GRU, Seq2Seq and attention
- Transformer architecture and Vision Transformers
- Autoencoders, VAEs, GANs and diffusion models
- ONNX, quantisation and TensorFlow Lite
- NLP workflow, text collection and regex for NLP
- NLTK, spaCy, TextBlob, Gensim and Hugging Face
- Cleaning, tokenisation, stemming and lemmatisation
- POS tagging, dependency parsing and Hinglish / Indian-language text
- Bag of Words, N-grams, TF-IDF and text similarity
- Text classification, NER and topic modelling (LDA, NMF)
- Word2Vec, GloVe, FastText and Sentence-BERT
- LSTM / BiLSTM text models and Seq2Seq translation
- Subword tokenisation, BERT family, GPT, T5 and BART
- Hugging Face fine-tuning, summarisation and QA systems
- BLEU, ROUGE, METEOR and perplexity
- How LLMs are trained and aligned (SFT, RLHF, DPO)
- Generation parameters and the LLM landscape
- OpenAI, Anthropic and Gemini APIs; structured outputs
- Running open-source LLMs with Ollama; tokens, cost and latency
- Prompt patterns, chain-of-thought and templates
- Managing system prompts, history and memory
- Vector databases: FAISS, ChromaDB, Pinecone, Qdrant
- Chunking, hybrid search, re-ranking and GraphRAG
- RAG evaluation with RAGAS
- LangChain and LlamaIndex
- LoRA / QLoRA fine-tuning; multimodal models, Whisper, Stable Diffusion
- Gen AI-assisted EDA, data cleaning and code generation
- Text-to-SQL and natural-language analytics
- Synthetic data generation and LLM-based data labelling
- Chatbots and copilots with Streamlit and Gradio
- Multimodal apps: vision-language models, speech and image generation
- Cost, latency and quality optimisation for Gen AI apps
- LLM evaluation, guardrails and responsible AI
- LangSmith / Langfuse, FastAPI, Docker and vLLM serving
Master Industry Tools Through Hands-On Practice
Pandas
Python
Numpy
SQL
Tensor Flow
AWS
Matplotlib
Scikit Learn
Gen AI
PyTorchBuild Real Projects. Showcase Your Skills

Car's Ex-Showroom Price Prediction
Predict car ex-showroom prices using machine learning based on features, specifications, and brand.
Kidney Stone Classification Project
Classify kidney stone cases using medical data and machine learning classification techniques.
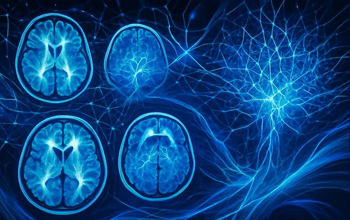
Brain Tumor Detection Using MRI Scan Images
Detect brain tumors from MRI scan images using image processing and deep learning models.
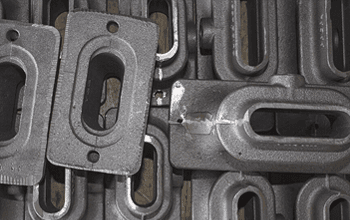
Casting Iron Defect Image Classification
Identify casting iron defects from images using computer vision and deep learning techniques.
SPAM Detection
Classify messages or emails as spam or legitimate using natural language processing and machine learning.
Recommendation System
Recommend relevant products or content based on user preferences, behavior, and historical data.
Earn an industry-recognised certificate
Showcase your skills and project experience with a Brillica Services certificate. Add it to your resume and LinkedIn profile to highlight your achievements, strengthen your professional credibility, and stand out to potential employers.
- Worldwide RecognitionShowcase your course completion and practical skills with a certificate from Brillica Services to support your professional profile when applying for opportunities.
- Lifetime ValidityYour certificate remains valid for a lifetime, allowing you to highlight your learning achievement throughout your career.
- Project-Based AchievementEarn your certificate by completing course requirements, projects, and assessments, demonstrating your practical learning beyond classroom attendance.
Our learners work at top companies
Our placement team prepares you for career opportunities across industries with expert guidance, interview preparation, and job-readiness support.
Built for Saharanpur's beginners and professionals who want a career in Data Science and AI
- Graduates and final-year students (B.Tech, BCA, MCA, B.Sc) in Saharanpur who want a first job in data science or AI.
- Software developers and testers moving into data science, machine learning and AI engineering.
- Data and business analysts who want to add Python, machine learning and Gen AI to their skills.
- Working professionals and career switchers who want a structured online path into AI.
- Founders and freelancers who want to use AI and data to automate work and decisions.

Learn from Industry Experts
Recently placed Brillica learners


Skills open the door. Confidence gets you the job.
Alongside your regular course, every Brillica learner goes through our Job-Readiness Program and Personal Development Program (PDP). Resume, communication, GD, aptitude, interview skills and mock interviews, until you're ready to crack the interview.
Resume building
One-on-one resume reviews with ATS-friendly templates for your target role.
Recruiter-ready resumeLinkedIn & portfolio
Optimised LinkedIn profile, GitHub, Behance or campaign portfolio from your course projects.
Profile that gets foundCommunication skills
Spoken English, email writing, presenting your projects and speaking with confidence.
Clear, confident speakingGroup discussion (GD)
Weekly GD rounds on tech, business and current topics with feedback on structure and clarity.
Clear the GD roundAptitude & reasoning
Quantitative, logical and verbal practice in the format used by campus and off-campus drives.
Pass screening testsInvest in your career, pay monthly
What's included
- Live classroom or online classes
- AI-infused curriculum & tools
- BrillicaNext LMS & app for 1 year
- Projects with mentor reviews
- Job-Readiness Program: resume, GD, mock interviews
- Placement drives & referrals
- Industry-recognised certificate
About Advanced Data Science Course in Saharanpur with Gen AI
In today’s fast-changing digital world, Data Science has become one of the most in-demand and high-paying career options. With the rapid growth of Artificial Intelligence, Machine Learning, and Generative AI (Gen AI), companies are looking for skilled professionals who can work with data and intelligent systems. If you want to build a strong and future-ready career, enrolling in a Data Science course in Saharanpur with Gen AI is the right step.
Brillica Services offers a job-oriented Data Science online course designed to deliver practical skills, real-world experience, and industry-ready knowledge. Because of its quality training and strong career support, Brillica Services is the best institute for Data Science course in Saharanpur and a trusted Data Science institute for learners at all levels.
About the Data Science Course
The Advanced Data Science course with Gen AI in Saharanpur at Brillica Services is designed for students, freshers, and working professionals who want to become job-ready in Data Science and AI. This data science course follows a hands-on learning approach and covers everything from Python programming and data analysis to machine learning, deep learning, and Gen AI applications.
With live projects, expert guidance, and real industry use cases, this online course helps learners gain practical exposure and confidence to work in real professional environments.
Why Choose a Data Science Course with Gen AI?
Generative AI is transforming industries such as healthcare, finance, IT, e-commerce, and marketing. Unlike traditional AI, Gen AI can create text, images, predictions, and smart automated solutions.
By joining the Data Science course in Saharanpur with Gen AI, you will:
- Learn core and advanced Data Science concepts
- Work with tools like Python, SQL, Power BI, TensorFlow, and PyTorch
- Use Gen AI tools such as ChatGPT and Large Language Models
- Build real-world projects like prediction models and AI systems
- Earn an industry-recognized Certification from Brillica Services
Who Can Join This Data Science Course in Saharanpur?
This data science course is suitable for:
- Students (12th pass or graduates) starting a tech career
- Working professionals from IT, analytics, or finance backgrounds
- Entrepreneurs and freelancers using AI for business growth
- Anyone interested in Data Science, AI, and Gen AI
- No prior coding knowledge is required.
Data Science Course Curriculum with Gen AI
The Data Science course in Saharanpur with Gen AI includes:
- Introduction to Data Science, AI, ML, and Gen AI
- Python, NumPy, Pandas, and data handling
- Data cleaning, preprocessing, and analysis
- SQL and database management
- Statistics and probability concepts
- Machine learning and model building
- Deep learning with neural networks
- Generative AI, ChatGPT, LLMs, and prompt engineering
- Data visualization using Power BI and Tableau
- Capstone projects such as fraud detection, chatbots, and sales forecasting
Tools and Technologies Covered
During the Data Science online course, you will work with:
- Python, R, SQL
- TensorFlow, PyTorch, Keras, Scikit-learn
- Power BI, Tableau, Matplotlib
- OpenAI, Google AI, Hugging Face, Azure AI
Career Opportunities After the Data Science Course
After completing the Data Science course in Saharanpur with Gen AI, you can apply for roles such as:
- Data Scientist
- Data Analyst
- Machine Learning Engineer
- AI Engineer
- Gen AI Specialist
- Business Intelligence Analyst
The demand for skilled Data Science professionals is growing rapidly, offering excellent salary packages and global career opportunities.
Why Choose Brillica Services?
Brillica Services focuses on practical learning and career success.
Key Benefits:
- Industry-experienced trainers
- Hands-on learning with live projects
- Flexible online course options
- 100% placement assistance and career support
- Industry-recognized Certification
Because of these benefits, Brillica Services is the best institute for Data Science course in Saharanpur.
Final Words
Data is shaping every industry, and Artificial Intelligence is defining the future. Learning Data Science with Gen AI gives you a strong edge in today’s competitive job market.
Enroll now in the Data Science course in Saharanpur with Gen AI at Brillica Services and start your journey toward a successful and future-ready career in Data Science and Artificial Intelligence.
Advanced Data Science Course in Saharanpur with Gen AI: FAQs
Start your Advanced Data Science Course in Saharanpur with Gen AI journey
Speak with our counsellor today to explore course fees and secure your admission with no-cost EMI.